AI FACTORY

Manufacture Intelligence at Industrial Scale

Turn AI capabilities into industrial-scale intelligence with the compute, data, and infrastructure to make it happen.

Let's Build Your AI Factory

Talk to a Netweb AI infrastructure specialist

Tell us where you're starting from and we'll come back with a sized, priced configuration built around our solutions.

Single point of contact from design to deployment
NVIDIA-validated rack & liquid-cooling designs
Sizing from 4 to 1000+ GPUs

Request AI Factory Consultation

Fill in the details below — our specialist will reach out within one business day.

1 Contact Details
2 Project Details
Please enter your name.
Please enter your company name.
Please enter a valid work email.
Please enter a valid phone number.
Please enter your location.
Workloads

Which AI Workloads Are You Looking to Power?

An Enterprise AI Factory is a purpose-built, full-stack platform for manufacturing intelligence at scale across on-premises and hybrid environments. Based on NVIDIA Reference Architectures, it combines accelerated computing, networking, storage, software, models, data, and security to power agentic AI, physical AI, inference, training, analytics, HPC, and simulation. Explore the workloads below to identify the capabilities that align with your AI initiatives.

Deploy AI agents or copilots

Long-running agents that plan, call tools, and execute multi-step work — not just answer questions.

  • Enterprise copilots & coding agents
  • Customer support agents with tool access
  • Multi-agent orchestration pipelines

Train or fine-tune models

From foundation model pretraining to fine-tuning on your own proprietary enterprise data.

  • Domain-specific LLM fine-tuning
  • Fraud & risk model training (BFSI)
  • Foundation model pretraining at scale

Run inference at scale

High-throughput, low-latency inference including RAG and enterprise search.

  • Real-time fraud & transaction scoring
  • Retrieval-augmented knowledge search & compliance lookup
  • Trillion-parameter model serving

HPC or scientific computing

Compute-intensive research and engineering workloads that predate AI but now run alongside it.

  • Genomics & drug discovery pipelines
  • Seismic & subsurface interpretation (energy)
  • Computational fluid dynamics (CFD)
Benefits

Powering AI Performance, Efficiency and Control

Ignite your competitive edge and manufacture digital intelligence at scale with the Tyrone AI Factory – built on NVIDIA Reference Architecture. Experience unprecedented efficiency, accelerate AI reasoning, and future-proof innovation for tomorrow.

Optimize AI Economics

Owning infrastructure optimizes the cost of intelligence — GPU utilization, token throughput, and performance per watt — not just the acquisition price.

Faster decision to deployment

Validated, NVIDIA-certified designs eliminate the guesswork and integration risk of building sovereign infrastructure.

Security and governance

Enterprise AI Factories provide the observability, policy control, isolation, and data protection required for production AI. NVIDIA technologies and reference designs provide layered protections for data, models, agents, & credentials.

Future-Ready Infrastructure

NVIDIA Reference Architectures provide a stable foundation for Enterprise AI Factories that can absorb ongoing innovation across NVIDIA ecosystem.

Accelerate Time to Token

Leverage NVIDIA’s structured approach and recommended designs to deploy AI solutions faster and accelerate time to business value.

Resource and Cost Efficiency

Optimized configurations improve resource utilization, minimize waste, and reduce overall costs.

Risk Mitigation

Proven and tested design patterns increase customer confidence, reduce deployment risk, and help ensure consistent, predictable outcomes.

Supportability

Standardized design patterns promote consistency across deployments, reduce support requirements, and enable faster issue resolution.

Performance

High-performance infrastructure meets the demanding requirements of AI workloads and helps ensure optimal performance.

Scale and Manageability

Flexible scaling options and manageable configurations enable enterprises to grow their AI infrastructure seamlessly.

Reduced Complexity and TCO

Simplified deployment processes and efficient designs reduce operational complexity and total cost of ownership.

AI LIFECYCLE

Build the Complete AI Factory

From data to intelligence.

Netweb brings together data, private cloud, accelerated compute, high-performance storage and intelligent workload management into one integrated AI Factory built to scale AI from data to intelligence.

FMOcean

Prepare your data

Most AI initiatives stall before training even starts — data locked in silos, no consistent pipeline, no MLOps discipline to keep it usable. FMOcean unifies data pipelines, ETL/ELT integration, data management and FM Ops/MLOps into one platform, so your factory starts on clean, governed, AI-ready data instead of a data swamp.

See how FMOcean gets your data AI-ready →
AI-ready servers, GB200 NVL4 to RTX PRO 6000

Choose your compute. Scale your AI factory.

From department-scale systems to rack-scale and multi-POD architectures — the compute tiers inside this stage.

NVIDIA GB200 NVL4

Department-Scale Grace Blackwell

  • 4× NVIDIA Blackwell GPUs
  • 1.8TB fast memory
  • 32TB/s bandwidth
Best for: AI development, enterprise AI, department-scale workloads

NVIDIA GB200 NVL72

Rack-Scale AI Performance

  • 72× NVIDIA Blackwell GPUs
  • Up to 13.5TB HBM3e
  • 130TB/s NVLink bandwidth
Best for: Large-scale AI training and demanding HPC workloads

NVIDIA GB300 NVL72

NVIDIA Blackwell Ultra at Rack Scale

  • 72× NVIDIA Blackwell Ultra GPUs
  • Up to 20TB GPU memory
Best for: Trillion-parameter models and real-time inference

NVIDIA HGX™ B300 Scale-Out

Scale from Rack to Multi-POD

  • 8-GPU HGX B300 baseboard
  • PCIe Gen5 storage architecture
Best for: Scalable AI clusters and multi-rack deployments

NVIDIA RTX PRO™ 6000 Blackwell Server Edition

Universal AI & Visual Computing

  • 96GB GDDR7 per GPU
  • Passive-cooled
  • Multi-GPU server-optimised
Best for: Inference, fine-tuning, HPC and virtual workstations at flexible scale
Skylus Private Cloud

Build your cloud

Public cloud AI spend spirals unpredictably and your data leaves your control; pure on-prem infrastructure lacks the agility teams expect. Skylus Private Cloud unifies compute, storage and networking into a private, hyper-converged AI factory — deploy faster, manage simpler, and scale without giving up sovereignty over your data or your economics.

Skylus Private Cloud Brochure →
Maximize GPU utilization

Maximize GPU utilization

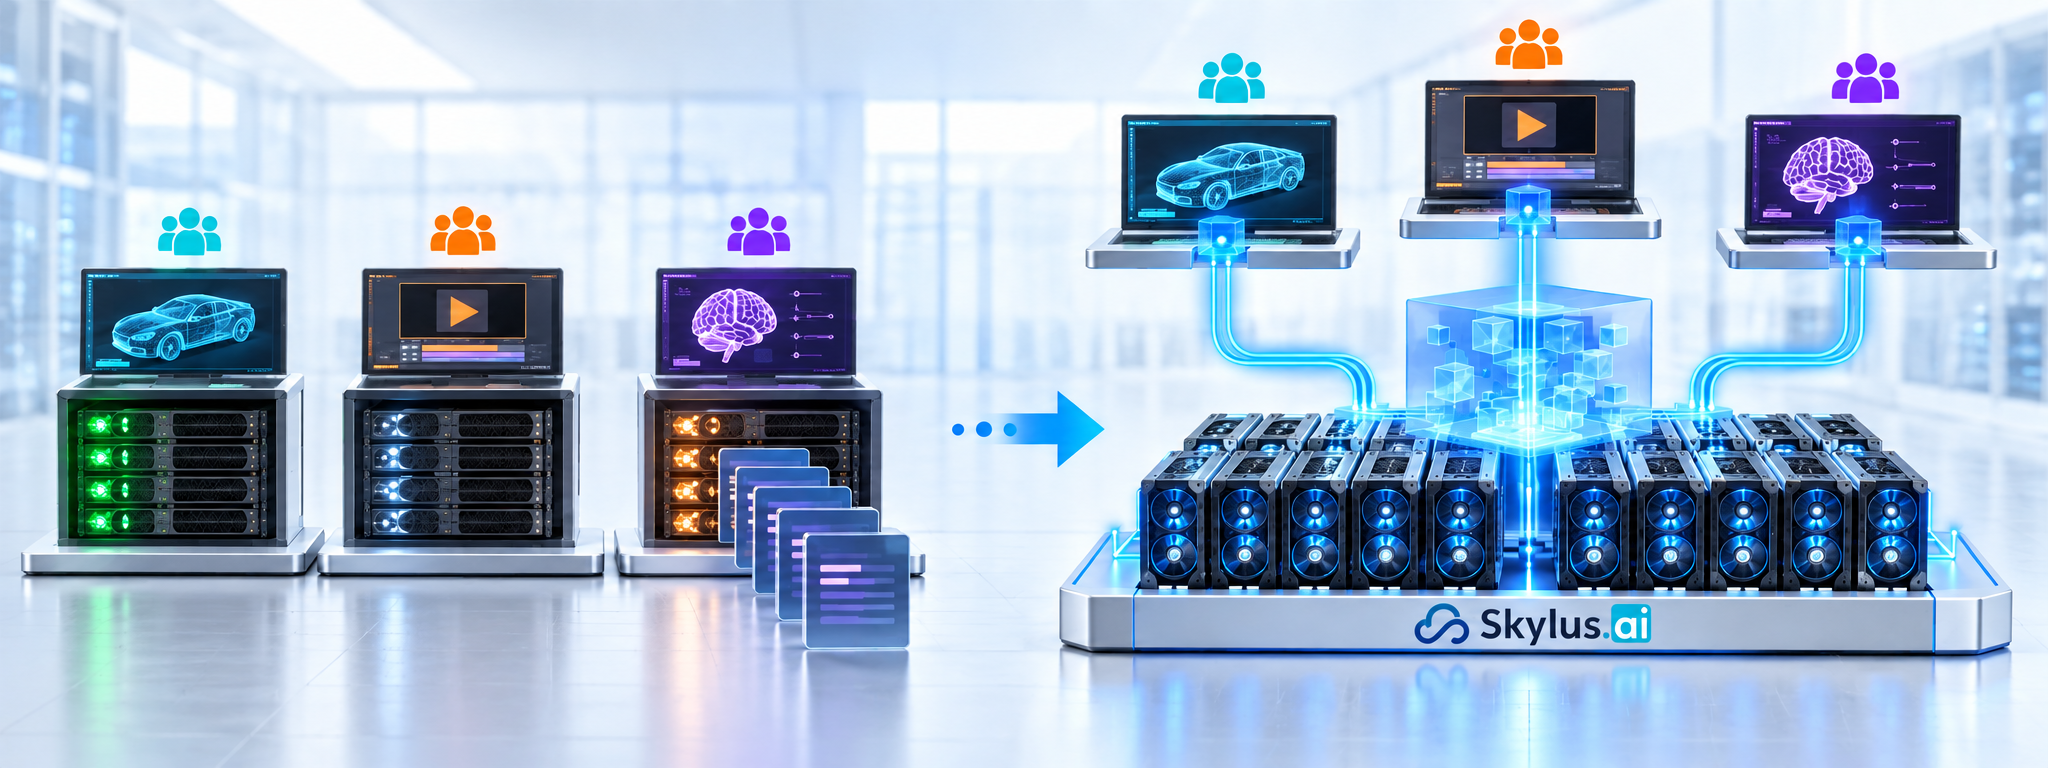
Static GPU allocation means one team's cluster sits idle while another queues jobs for days. Skylus.ai composably aggregates and disaggregates GPU resources across the factory including for generative AI workloads — so every GPU is pooled and routed to where it's actually needed.

Skylus.ai Brochure →
Kubyts

Accelerate ML development

Your data scientists are fighting infrastructure, not building models.

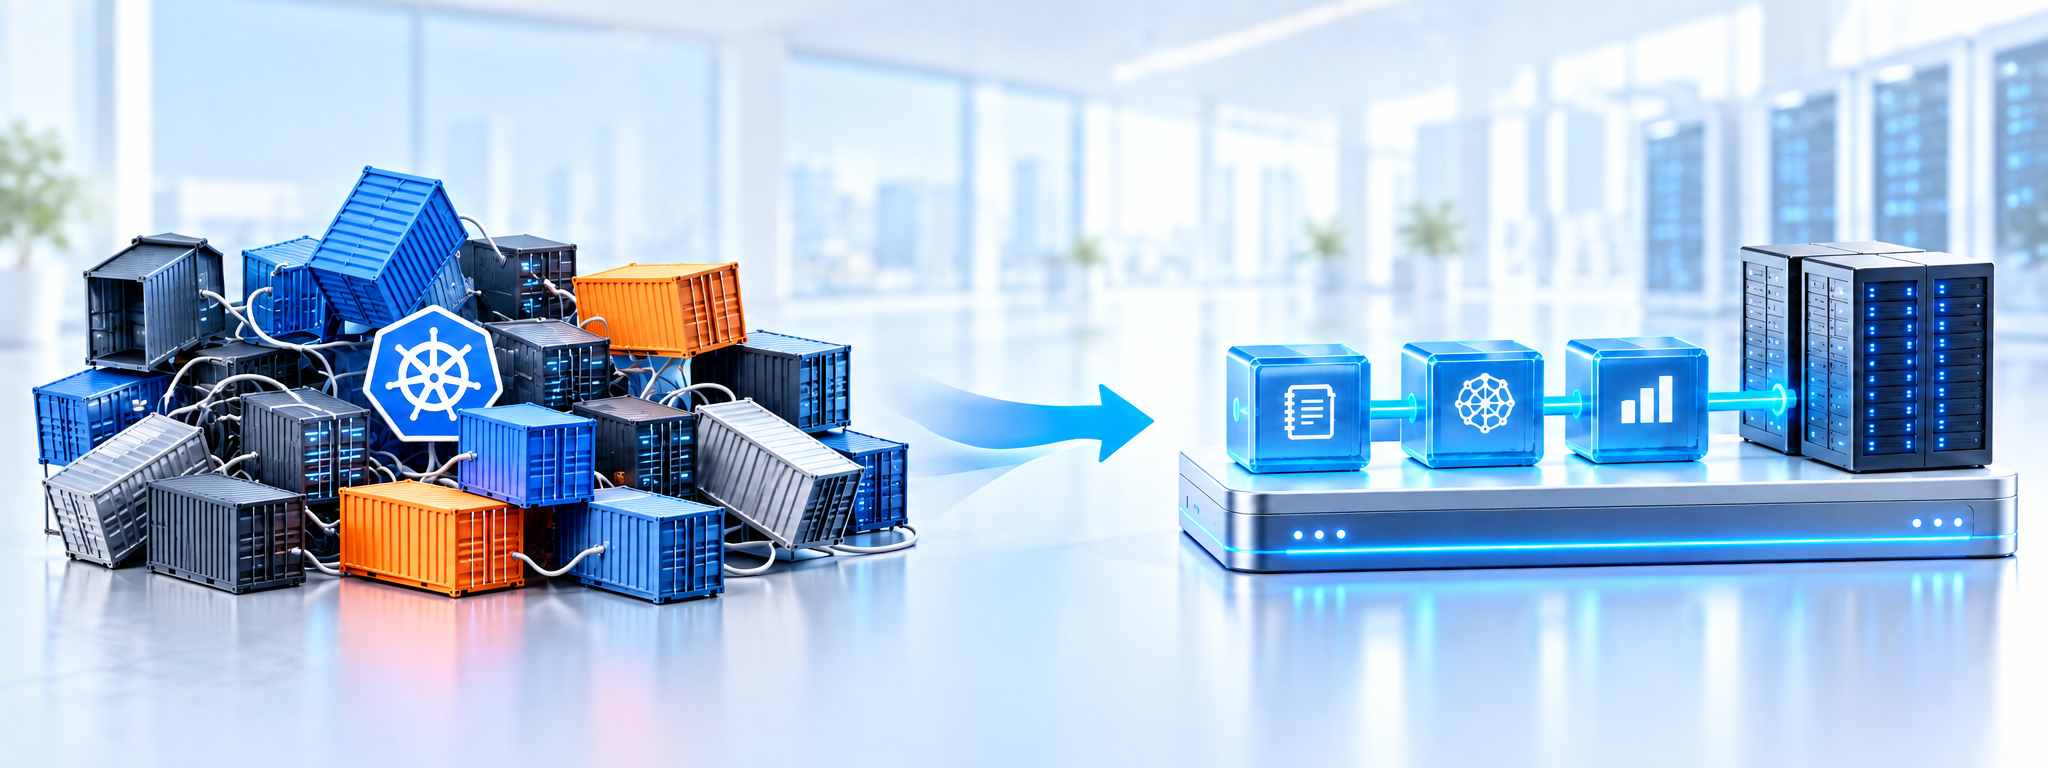
Container sprawl and Kubernetes overhead slow ML teams down before experimentation even starts. Kubyts gives you container-optimised infrastructure purpose-built for machine learning and deep learning, so training and inference pipelines move from notebook to production without a platform-engineering detour.

Kubyts Brochure →
Verta Storage

Feed compute at scale

A cluster of GPUs idling on I/O is capital sitting still. VERTA delivers flexible, high-performance storage for demanding AI/HPC environments; ParallelStor is engineered specifically for AI, HPC and container throughput; VELOX unifies flash, high-performance disk, tape and cloud into one high-IOPS global namespace.

Compare storage options →
Tyrone Cluster Manager

Manage & scale the cluster

More nodes and more GPUs mean more blind spots — queued jobs, dropping utilization, failures no one notices until a deadline slips. Tyrone Cluster Manager centralizes deployment, monitoring and utilization across your HPC and AI environment, so scaling from one rack to many doesn't mean losing operational control.

Tyrone Cluster Manager Brochure →
Tyrone Cluster Manager

Bring Intelligence Home

Build, deploy and manage Generative AI on your own infrastructure with Tyrone IntuixAI. Maintain greater control over your data, models and AI operations while turning enterprise data into actionable intelligence.

Explore IntuixAI →
Why Netweb?

Reliability you can count on

Netweb Technologies designs, manufactures, and deploys infrastructure backed by our rack engineering and liquid-cooling expertise.

Engineered & assembled in India

Rack, tray, and cabling designs built and validated in Netweb's own facilities under the Tyrone product line.

NVIDIA-certified building blocks

NVIDIA Grace Blackwell Superchips, NVIDIA NVLink™, NVIDIA ConnectX® SuperNIC™, and NVIDIA BlueField®-3 DPU — sourced and integrated to NVIDIA Reference Architectures.

End-to-end deployment

Rack, CDU liquid cooling, busbar power, and network fit-out delivered as one project, not separate vendors.

Scales with you

From solution design to deployment and long-term support, Netweb helps your AI infrastructure evolve with your needs.

Built on NVIDIA Reference Architecture

Tyrone AI Factory systems are engineered to NVIDIA's HGX AI Factory, RTX PRO AI Factory and NVL72 AI Factory Reference Architectures. Every configuration passes NVIDIA's certified-systems testing: thermal analysis, mechanical stress testing, power consumption evaluation and signal integrity assessment so you're deploying a validated design, not a one-off build.